Description#
This challenge focuses on open-source intelligence (OSINT) and how publicly available information can be pieced together to answer investigative questions. The goal is to practice extracting useful facts from domain records, archived web pages, and image-based searches while staying within legitimate public data sources.
Solution#
The investigation relies on three main sources: domain registration data, archived website snapshots, and a reverse image search.
Q1: Who is the registrar for
jameskainth.com?
I checked the domain with the whois command and inspected the registration details:
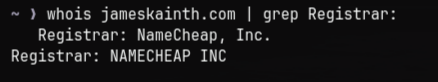
Flag: NameCheap
Q2: What is the Zoom meeting ID of the British Prime Minister’s Cabinet Meeting?
I found the article that leaked the meeting details on the public web and confirmed the Zoom ID from that report:
The Cabinet meeting Zoom leak article
Flag: 539544323
Q3: In 2019, UVM’s Ichthyology class had to name a fish for class. What was the most recently assigned fish name?
I started with a Brave search for the class and found the course page that referenced the fish-naming assignment:
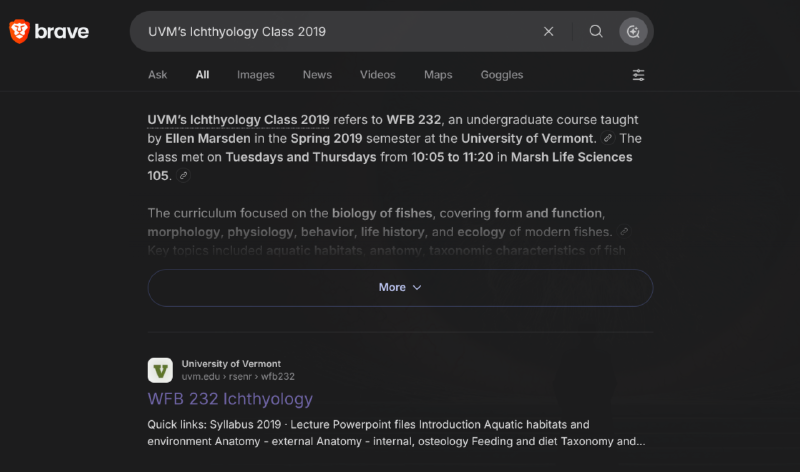
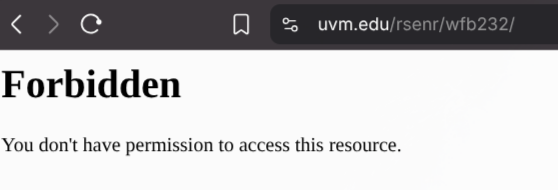
The first result pointed to the course website, but access to the live page was restricted.
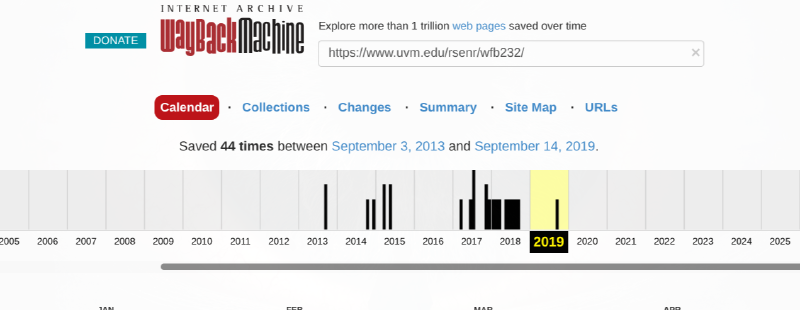
I used Wayback Machine to view the archived page and found a snapshot from September 2019 that included a link to the student fish names document.
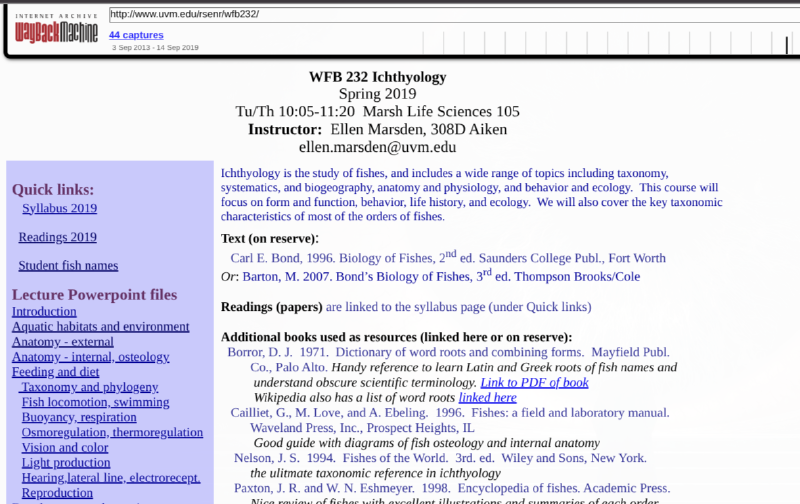
The spreadsheet contained the fish names in order, and the most recent entry was the last one in the file.
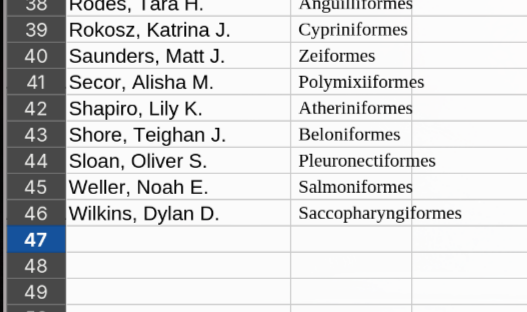
Flag: Saccopharyngiformes
Q4: Can you identify the state from which this picture was taken?
I uploaded the image to Google Lens and the reverse image search identified the location as a tourist attraction in Virginia.
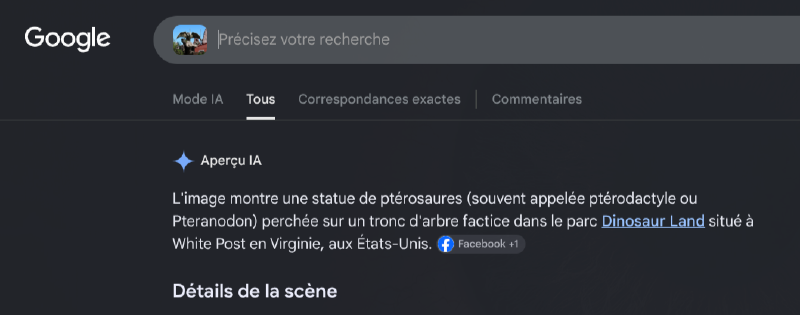
Flag: Virginia
I used AI to check spelling and improve the phrasing of this writeup. No AI was used to solve the challenge itself.